Understanding the True Computer-Assisted Translation Meaning in Modern Workflows
Many organisations assume that routing a sensitive medical transcript or a complex legal contract through software is identical to translating it. They treat human language as a mathematics equation where one vocabulary word cleanly substitutes for another, completely ignoring the fact that a literal, word-for-word match often destroys the actual instruction. This assumption leads hospitals, courts, and corporate entities to deploy automated systems in high-stakes environments, only to discover later that the output was grammatically flawless but functionally dangerous. The distinction between a human linguist supported by software and an algorithm left to its own devices is not a minor technical detail. It is the boundary between safe communication and severe liability. Understanding how language technology actually operates requires breaking down the mechanisms that separate human cognition from predictive text generation.
Quick Summary
The true computer-assisted translation meaning refers to human linguists using software environments to manage terminology and recall previous work, rather than relying on algorithms to perform the translation itself. While automated tools predict text patterns, human-driven workflows ensure domain accuracy.
- Software tools segment text to help human translators maintain consistency across large projects.
- Translation Memory (TM) databases store previous human translations to prevent redundant work.
- High-stakes environments require distinct workflows for text processing versus live spoken interpreting.
- Effective knowledge transfer depends on human emotional intelligence and cultural context, not just vocabulary.
Table of Contents
- The Actual Computer-Assisted Translation Meaning
- Where Machine Translation Breaks Down
- The Mechanics of Knowledge Translation
- How Modern Translation Workflows Actually Operate
- The Cost of Treating Translation as a Commodity
- Why Live Interpreting Resists Automation
- Comparison Table: Language Technologies
- FAQ
- Recommended Reads
The Actual Computer-Assisted Translation Meaning
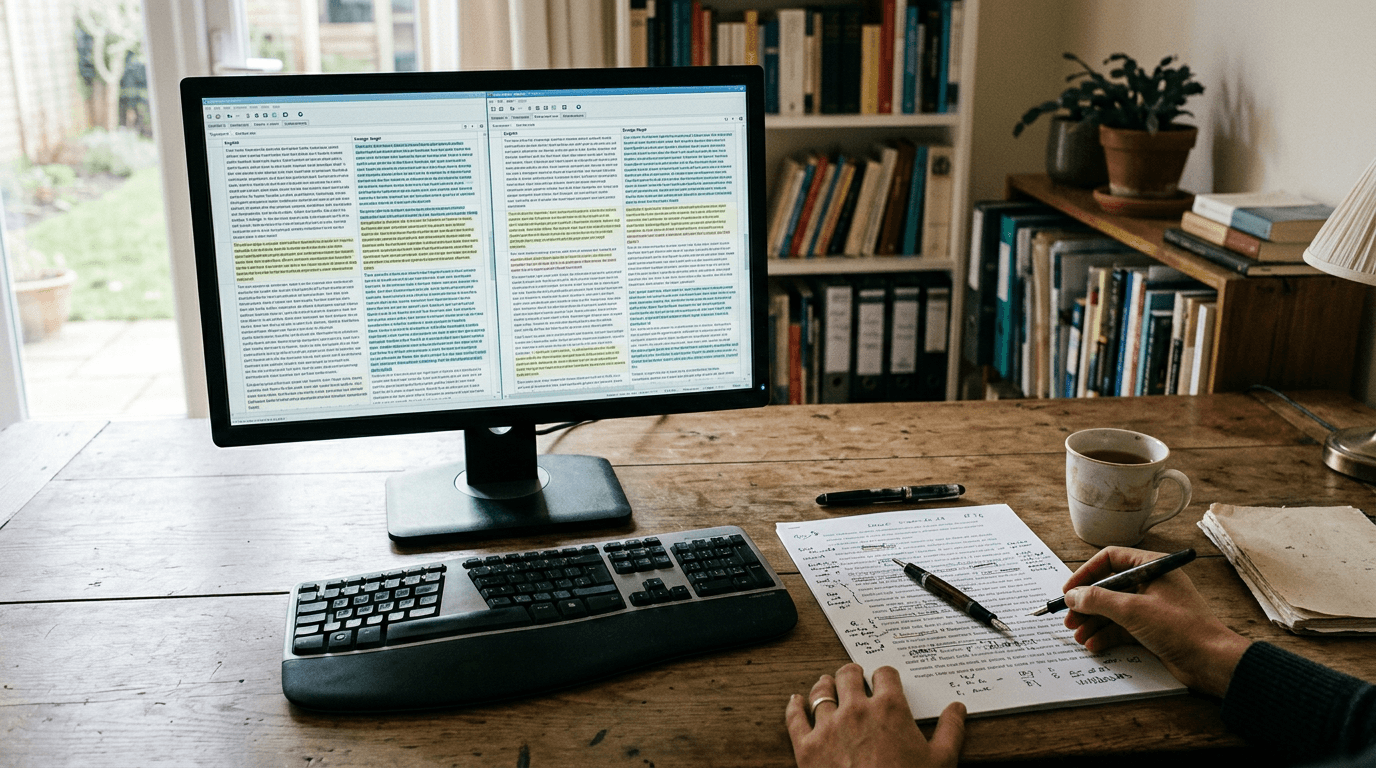
Understanding the true computer-assisted translation meaning is the first step in auditing any organisation's language operations. Often abbreviated as CAT, this term describes a software environment designed specifically for human linguists. The software does not translate the text. Instead, it breaks a source document down into manageable segments, usually sentences or short paragraphs, and presents them to a human professional in a bilingual grid. As the linguist translates each segment, the software saves both the original source text and the new target text as a paired unit into a database known as a Translation Memory (TM).
When project managers search for the computer assisted translation meaning, they are often confusing it with fully automated systems. The core mechanism of a CAT tool is repetition leverage. If a human translator encounters a sentence that is identical or highly similar to one they have translated before, the software retrieves the previous pairing and suggests it. The linguist then decides whether to accept the suggestion, modify it to fit a new context, or reject it entirely. This mechanism is critical for large technical manuals, clinical trial protocols, or software localisation projects where specific phrases repeat hundreds of times.
Beyond the Translation Memory, these environments enforce terminology compliance. Organisations load approved glossaries, known as termbases, into the software. When a recognized term appears in the source segment, the software highlights it and displays the approved translation. This prevents a scenario where three different linguists working on the same legal contract translate a specific statutory term three different ways. The tool enforces consistency, but the cognitive heavy lifting, the understanding of nuance, tone, and domain-specific intent, remains entirely with the human operator.
Practical rule: Never allow a vendor to use your proprietary Translation Memory databases to train public automated engines without a strict, audited data ring-fencing agreement in place.
Where Machine Translation Breaks Down
The operational mechanics of machine translation differ fundamentally from human-driven software environments. Modern automated systems rely on Neural Machine Translation (NMT) architectures. These systems do not understand language; they analyse vast datasets of bilingual text and use deep learning models to predict the most statistically probable sequence of words in the target language. They operate via attention mechanisms, assigning mathematical weights to different words in a source sentence to determine how they influence the target output.
The primary failure mode of neural systems in professional environments is the "fluent hallucination." Older, statistical automated engines produced output that was noticeably clunky and robotic, immediately alerting the reader that the text was generated by software. Neural engines, however, excel at producing grammatically perfect sentences that sound highly natural to a native speaker. The danger arises when the engine encounters a complex, ambiguous, or highly specialized phrase it cannot accurately predict. Instead of failing visibly, the engine will often confidently generate a perfectly fluent sentence that means the exact opposite of the source text, or drops a critical negative particle entirely.
In medical and legal settings, this failure mode carries severe consequences. If an algorithm misinterprets the dosage instructions on a discharge summary or reverses the liability clause in a commercial lease, the fact that the resulting sentence was grammatically correct offers no defense against the resulting harm. Automated engines lack real-world grounding. They cannot recognize when a predicted output violates physical laws, clinical safety protocols, or common sense. They cannot pause to ask a clarifying question about an ambiguous antecedent.
The Mechanics of Knowledge Translation
Language transfer is only one layer of the communication challenge; the deeper layer is knowledge translation. In clinical, legal, and government environments, this concept involves adapting complex domain expertise into concepts that are accessible and actionable for the end user. It requires crossing both linguistic barriers and barriers of health or legal literacy.
When a specialist communicates with a vulnerable individual or a layperson from a different cultural background, simply providing a literal translation of specialist terminology fails the core objective of the interaction. If a medical professional explains an oncology treatment protocol, the interpreter or translator must navigate the cultural perception of the disease, the patient's baseline understanding of human anatomy, and the specific emotional weight of the diagnosis. A literal dictionary match for clinical terms may technically be correct while remaining completely incomprehensible to the patient.
This is why human practitioners apply contextual adaptation. A professional must assess the listener's comprehension in real-time, reading non-verbal cues and adjusting the register of the language without altering the clinical or legal accuracy of the message. This requires a high degree of emotional intelligence and domain competence. The practitioner acts as a bridge between a highly regulated, technical system and a human being navigating that system. Automation tools can retrieve vocabulary, but they cannot assess whether the listener is nodding in genuine comprehension or merely nodding out of cultural deference while remaining entirely confused.
How Modern Translation Workflows Actually Operate
Professional language service providers rarely rely on a single technology or a purely manual process. The standard approach for large-scale text processing is a hybrid workflow designed to balance speed, cost, and risk. The first stage of this workflow is file preparation and analysis. Source documents are parsed through software to strip out formatting tags, isolate the translatable text, and compare it against existing Translation Memory databases.
If a project contains highly repetitive, low-risk content, such as internal server logs or basic product descriptions, the workflow may incorporate an automated pass. This is where an algorithm generates a first draft. However, professional standards dictate that this draft must proceed to Machine Translation Post-Editing (MTPE). In this phase, a qualified human linguist reviews the algorithmic output, correcting structural errors, fixing terminology violations, and rewriting hallucinatory sentences.
Organizations must clearly classify their content risk before choosing a workflow. High-stakes content, such as informed consent forms, evidentiary documents, or patient-facing public health warnings, typically bypasses the automated draft stage entirely. These materials are routed directly to human linguists operating within secure CAT environments. The risk of a fluent hallucination slipping past a fatigued post-editor is deemed too high for critical materials. Ensuring that linguists and project managers have secure access to their tools is a fundamental requirement; professionals who Log In to Lingua Franca Hub | Secure Account Access understand that maintaining the integrity of the project environment is as important as the linguistic work itself.
The Cost of Treating Translation as a Commodity
A common failure in corporate and government procurement is treating language services as a raw commodity, evaluating providers solely on the lowest cost per word or the fastest turnaround time. This procurement model creates a perverse incentive for vendors to over-rely on unedited algorithmic output and bypass necessary quality assurance steps.
The hidden costs of this approach materialize downstream. When an organization publishes a poorly translated user manual, they experience increased support ticket volumes and warranty claims. When a hospital relies on ad-hoc bilingual staff or consumer-grade apps rather than professional services, they face increased readmission rates and severe malpractice liabilities stemming from lack of informed consent. The upfront savings of treating language as a commodity are entirely wiped out by the operational friction and legal exposure generated by inaccurate communication.
Practical rule: Audit your supply chain to ensure that your language service providers are paying their human linguists a sustainable rate; vendors competing exclusively on rock-bottom prices are invariably quietly substituting human expertise with unedited predictive text.
Why Live Interpreting Resists Automation
The technologies that assist with written text do not easily transfer to live, spoken environments. Written translation deals with static, finalized documents. The translator has time to research terminology, consult reference materials, and revise their phrasing. Live interpreting deals with dynamic, unpredictable human interaction.

Spoken language is messy. People do not speak in perfectly structured, grammatically complete sentences. They use false starts, they interrupt themselves, they speak over one another, and they rely heavily on implication, tone, and regional idioms. An interpreter processing this input must perform concurrent cognitive tasks: listening to the source language, deciphering the intended meaning through the noise of false starts and cultural nuance, formulating the equivalent concept in the target language, and delivering it aloud, all while already listening to the next sentence being spoken.
Algorithms require clean, structured input to function reliably. When fed the fragmented, overlapping, and context-dependent audio of a high-stress medical consultation or a hostile cross-examination, predictive models struggle severely. They cannot read the room. They cannot recognize that a speaker's sarcastic tone completely inverts the literal meaning of their words. For these reasons, providing Lingua Franca Hub | On-Demand Interpreting Services requires deploying verified human professionals who can navigate the immediate, chaotic reality of human conversation, ensuring that intent and emotion are transferred just as accurately as vocabulary. Protecting the data generated during these sensitive interactions is also paramount, governed strictly by frameworks detailed in the Privacy Policy | Lingua Franca Hub to ensure compliance with legal and medical privacy standards.
Comparison Table: Language Technologies
| Technology Category | Core Mechanism | Primary Failure Mode | Best Use Case |
|---|---|---|---|
| Computer-Assisted Translation (CAT) | Human-driven software; stores and retrieves past human work via Translation Memory. | Human fatigue; inconsistent terminology if glossaries are not strictly maintained. | High-stakes text translation, legal contracts, medical literature, repetitive manuals. |
| Neural Automated Engines | Deep learning algorithms predicting the most probable word sequences based on training data. | Fluent hallucinations; producing grammatically perfect sentences that are factually wrong. | Low-risk internal communications, bulk data triage, basic e-commerce descriptions. |
| Live Human Interpreting | Immediate cognitive processing of spoken language, accounting for tone, culture, and context. | Cognitive overload without adequate briefing or scheduled breaks. | Medical consultations, court hearings, sensitive corporate negotiations, crisis response. |
FAQ
What is the difference between CAT and automated engines?
CAT (Computer-Assisted Translation) is a software tool used by human professionals to manage formatting, ensure consistency, and recall previously translated sentences. Automated engines use algorithms to generate text without human intervention.
Can software replace human interpreters in medical settings?
No. Spoken language features false starts, interruptions, and heavy reliance on context and tone. Algorithms cannot reliably process unstructured clinical dialogue or read non-verbal patient cues, making human interpreters mandatory for clinical safety.
Why do automated engines sometimes produce completely wrong text that sounds natural?
Neural engines predict text based on statistical probability rather than actual comprehension. When faced with ambiguous or highly specialized input, they prioritize grammatical fluency over factual accuracy, resulting in fluent hallucinations.
What role does Translation Memory play in large projects?
Translation Memory saves paired source and target sentences translated by humans. When a similar sentence appears later, the software suggests the previous translation, ensuring consistency across hundreds of pages and reducing turnaround times.
How do professionals handle specialized terminology?
Human linguists use termbases (approved glossaries) integrated into their software environments. These databases highlight mandatory industry terms, ensuring that legal or medical vocabulary complies with regulatory standards throughout the document.